Laura Entis is a staff writer at Every.

How to Get the Most Out of Jev
Why the classification model is blowing up your timeline, how to turn subjective questions into Jev checks, and the dawn of intent-based software
Sep 23, 2026 · 9 min readUpdated Oct 15, 2026

Jev is fast, cheap, and accurate enough to handle the judgment calls you’d never pay an LLM to make at scale—is this email urgent, does this paragraph sound like AI, should I escalate this customer service request—on everything, all the time. Today, head of evals Mike Taylor explains what that unlocks, head of marketing Douglas Brundage shares his shortcut for putting Jev to work, and senior editor Jack Cheng shows why Jev is so good at turning intent into action.
Was this newsletter forwarded to you? Sign up to get it in your inbox.
Signal
Why Jev is blowing up your timeline
What happened: On September 15, TypeSafe, an AI frontier lab that spent two years in stealth, released Jev, a model that classifies text and structured data instead of generating it. The release lit a match that has yet to sputter: On X, Jev demos are everywhere. Users have gone viral showcasing how Jev can be used to play video games, re-rank search results, and filter social media posts, among so many other uses. Senior editor Jack Cheng’s Jev demo, which shows the model’s ability to infer a user’s intent from speech and hand gestures, has surpassed 1 million views.
Once you get your head around what Jev is and isn’t—it’s a decision model, not a chatbot—the fascination makes sense. Frame a task as a yes-or-no question, a multiple-choice pick, or a rating in plain English, and Jev returns a probability. Because it outputs probabilities rather than generating text one token at a time, Jev can answer huge batches of questions in parallel, almost instantly, and for a fraction of the cost of text-based LLMs.
What it means: Jev’s accuracy, speed, and dirt-cheapness unlock a world of possibilities. The model excels at classification at scale: It can, for example, sort your entire inbox archive into categories like newsletters, work messages, event invitations, etc., in less than a second. (Language models can do this, too, of course, but at a slower pace and at a much higher cost.) A general rule of thumb is that if a task is so simple that it would take a human less than 10 seconds to execute—such as determining how to classify an email—it’s a good use case for Jev. For tasks that require more reasoning and would take more than 10 seconds to complete, bring in the intelligence of a language model.
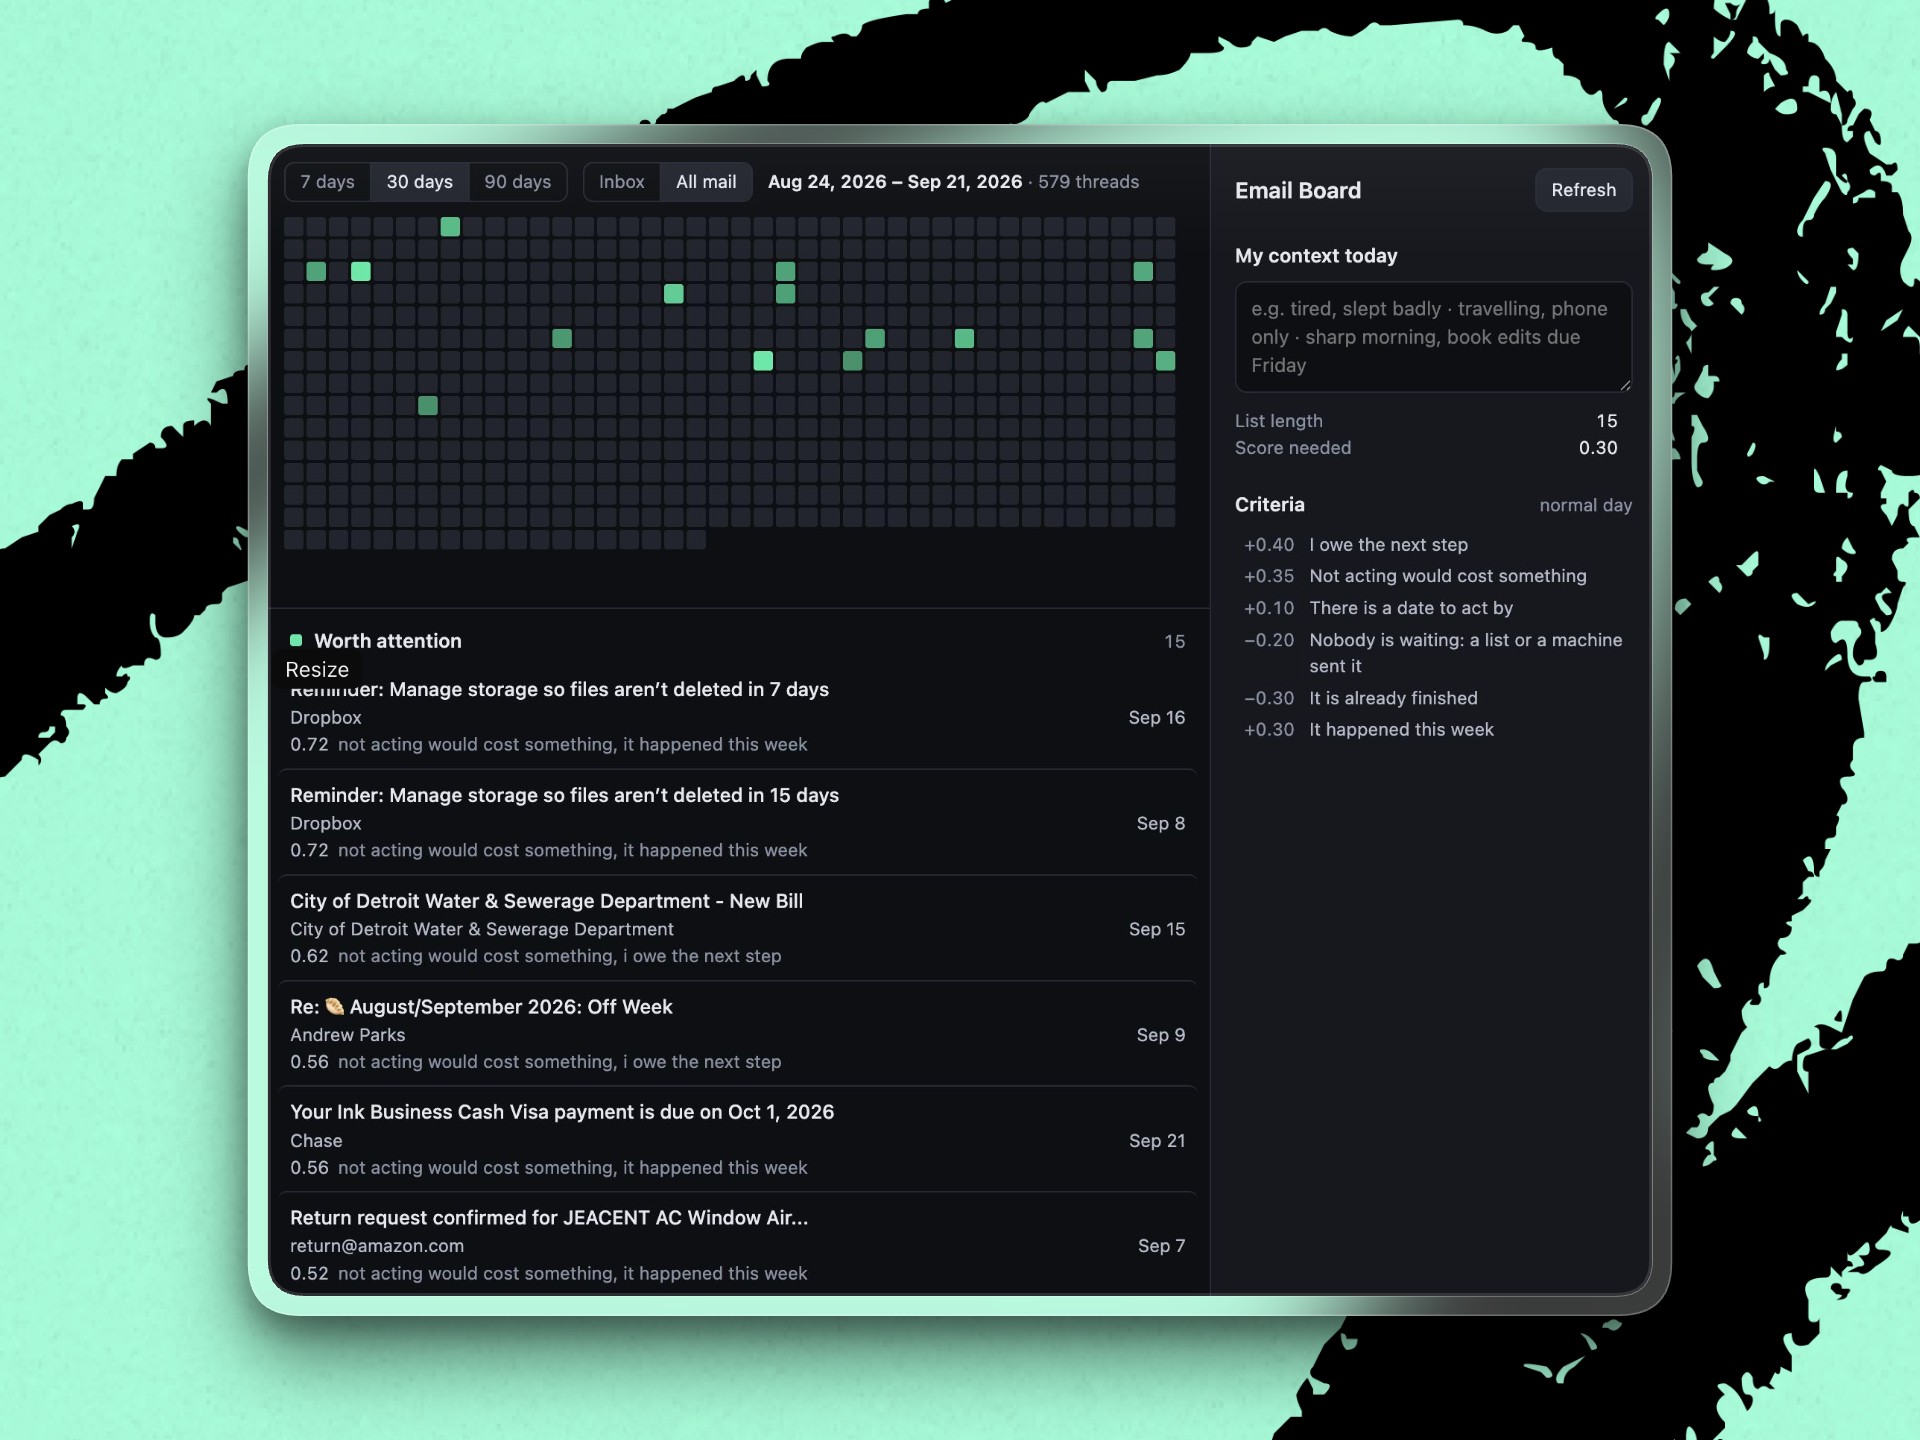
Sorting emails is straightforward. To use Jev for more complex, subjective calls such as “Is this email urgent?” you—or your agent—must first define urgency as a set of clearer checks: Was it sent by a human? Do you know the sender? Would ignoring it cost you something? Jev evaluates each question separately, and you can combine the scores in code to measure urgency.
The translation layer makes Jev less immediately intuitive to use than a chatbot LLM, but “it brings a lot of excitement back into programming,” says Mike. “Now it’s like, ‘Hey, if I could just be a little bit more creative with how I define this problem, I can do it 600 times cheaper.’”
Why it matters: Jev also plays nicely with traditional LLMs—think of it as a tool Codex or Claude Code can use to make narrow, high-volume judgment calls. This allows you to use the agent of your choice and send its outputs to Jev for real-time feedback. For example, you could draft an article in Codex and have it send the draft to Jev at every phase to check whether the article contains AI tells, Mike says. When a phrase is flagged by Jev, Codex can revise it on the spot. Or you could use Jev to determine which Slack messages, across all channels, meet your criteria for follow-up—and sort them into a personal feed in real time.
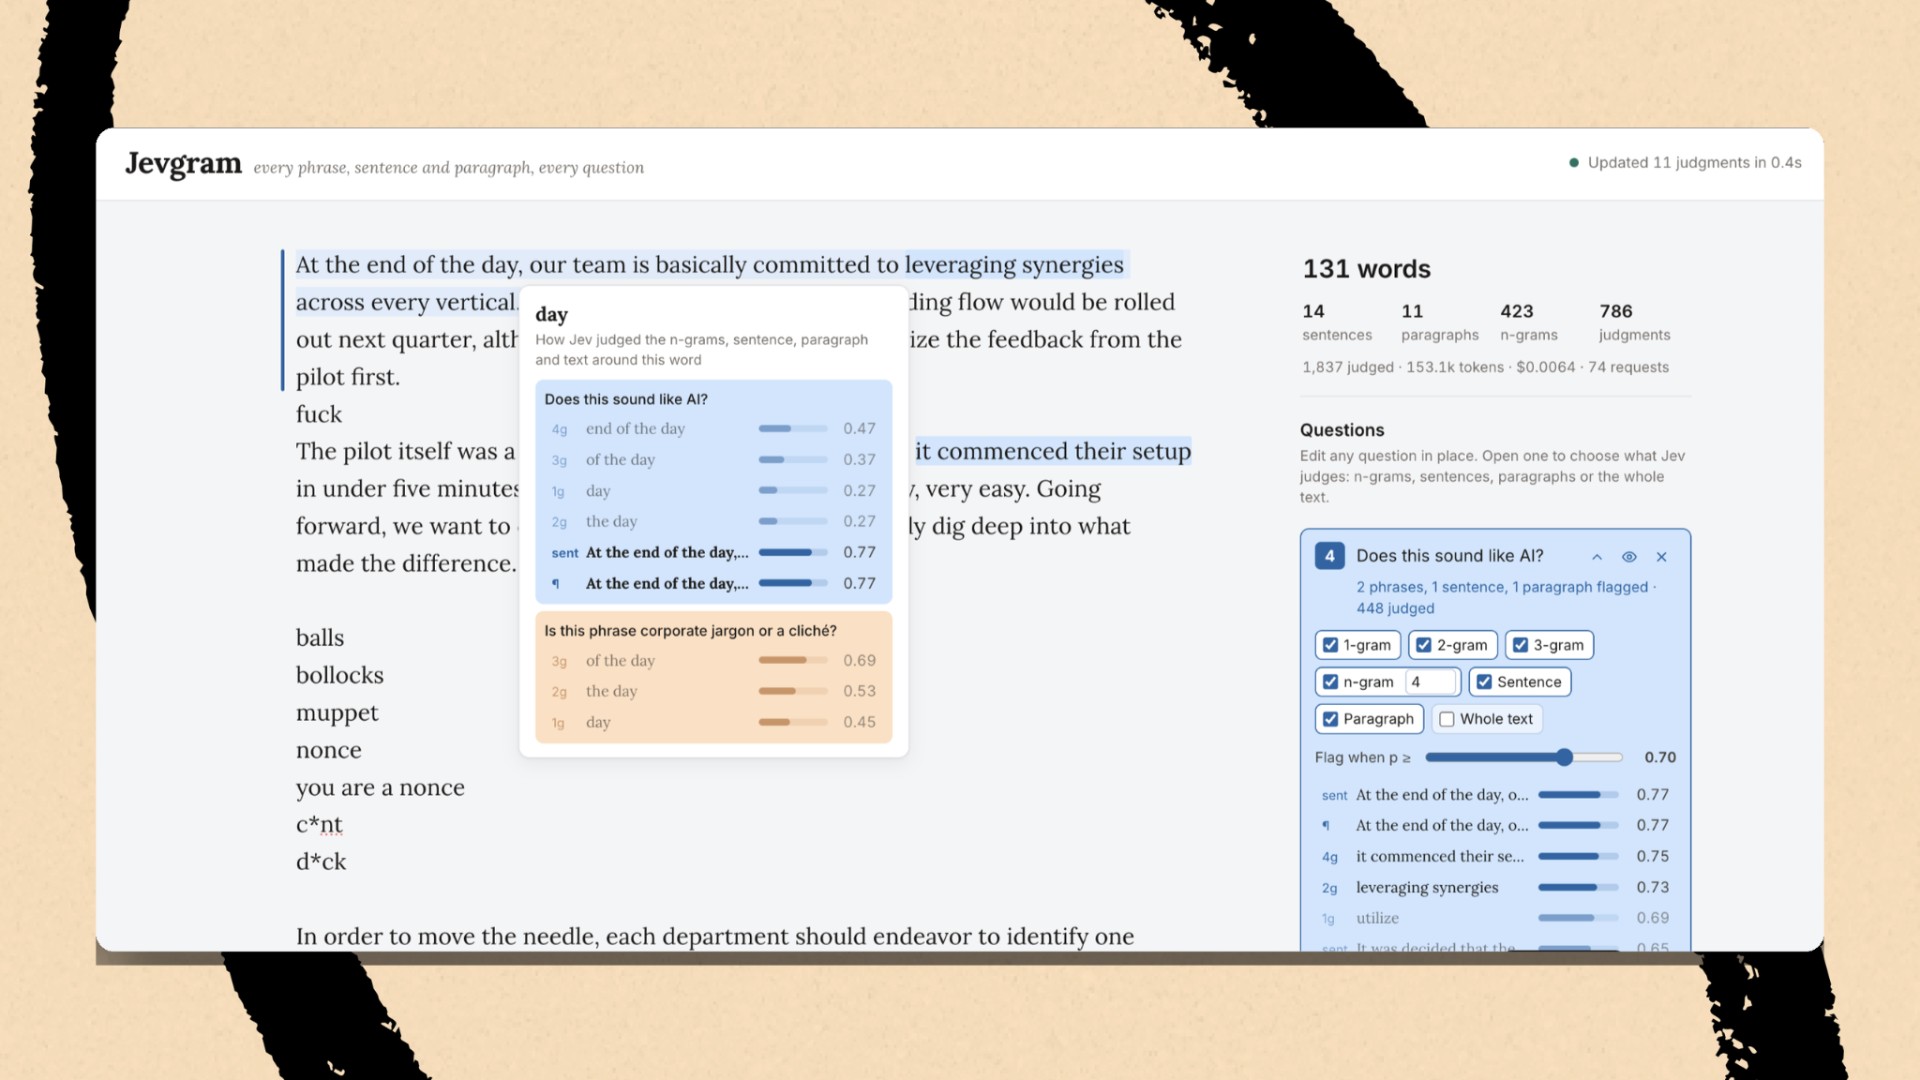
Jev lets you “check everything,” Mike says. “I think people are only just waking up to the implications of that.”
Steal this workflow
Turn a fuzzy question into Jev checks
Jev can classify text based on any question, including subjective ones. But queries like “Is this email urgent?” or “Does this writing sound like AI?” leave a lot open to interpretation. Breaking requests like these into specific checks gives you more control over what Jev evaluates—and makes it easier to investigate if its analysis differs from your own.
Step 1. Install the official TypeSafe skill. This gives your coding agent TypeSafe’s instructions for how Jev works and how to structure questions for it. Tell your agent to:
Install the official TypeSafe skill from https://github.com/typesafe-ai/skills, then use it to help me build this Jev workflow.
Step 2. Use AI to interrogate your intention. Ask Codex or Claude Code to define what “urgent,” “relevant,” or “worth reading” means to you.
Start with this prompt:
I want to use Jev to answer [subjective question] about [material], so I can [action or decision]. Ask me to share examples and explain why I would select some and reject others, including cases I’m unsure about. Use my answers to write a working definition.
Step 3. Break down your definition into discrete checks. To build a personalized email filter, Jack worked with Fable, which had access to his inbox, to develop weighted criteria:
- Did a real person write the message?
- Is someone he knows waiting on him?
- Will ignoring it cost him something?
He then ran those criteria across 90 days of email so he could have a personalized shortlist of messages that required his attention. The filter also helped him spot older messages that still required action from him.
Similarly, Mike suggests breaking a broad question like “Does this sound like AI?” into parallel checks that identify individual AI writing tells in a passage, such as “not X but Y” constructions or a tricolon of sentence fragments.
Ask your agent:
Turn our definition into questions Jev can assess separately. For each, define yes and no, give an example and a borderline case, and identify any context Jev needs. Use ordinary code for checks that don’t need AI. Explain how you’ll combine the results into [a shortlist, ranking, or flag], and what happens when information is missing.
Step 4. Judge whether you agree with the classifications. Jack’s initial email filter highlighted newsletters—not something he wanted marked as urgent—which prompted him to revise the criteria with Fable. When you disagree with Jev’s assessment for an item, check whether the instructions were unclear or any context was missing.
Use this prompt to refine your criteria:
Run the checks on a small sample I’ve already judged, without including my judgments in Jev’s input. Show what it selected and missed and compare that with my choices. Help me investigate disagreements and revise the checks. Then test on fresh examples I’ve judged before applying the revised checks to the full collection.
Save the questions and examples that produce useful results and use the revised instructions to classify your next batch of inputs so you can track improvements.
How We Write Now
Inside Mike Taylor’s AI writing workflow
Last week, Mike shared his 13 beliefs about writing with AI. In the newest entry in our How We Write Now series, he shows how those beliefs become finished pieces with a 12-step process that begins well before AI enters the picture. Read it here.
Want to watch Every’s writers work with AI in real time? Join Mike, Jack, and staff writer Katie Parrott for our Write-along tomorrow at 1 p.m. ET, live-streamed on X and YouTube.
Demo-spiration
Mine X for more ways to use Jev
If you’re unsure what to do with Jev, you’re not alone.
Luckily, there’s an easy solution—find a demo on X you’d like to copy, give it to your coding agent of choice, and ask it to adapt the demo for your workflow.
That’s the route Douglas took. He already had a Grok bot that delivered a morning report on agent-specific news, AI buzz, and cultural moments and suggested openings for Every to join the conversation. But “it wasn’t doing a great job,” he says.
Then Every CEO Dan Shipper shared a Jev demo in Slack from developer Elvis Sun, who had Jev read 384 news stories published in a single morning to tell 15 different brands which stories the brands should try to engage with online.
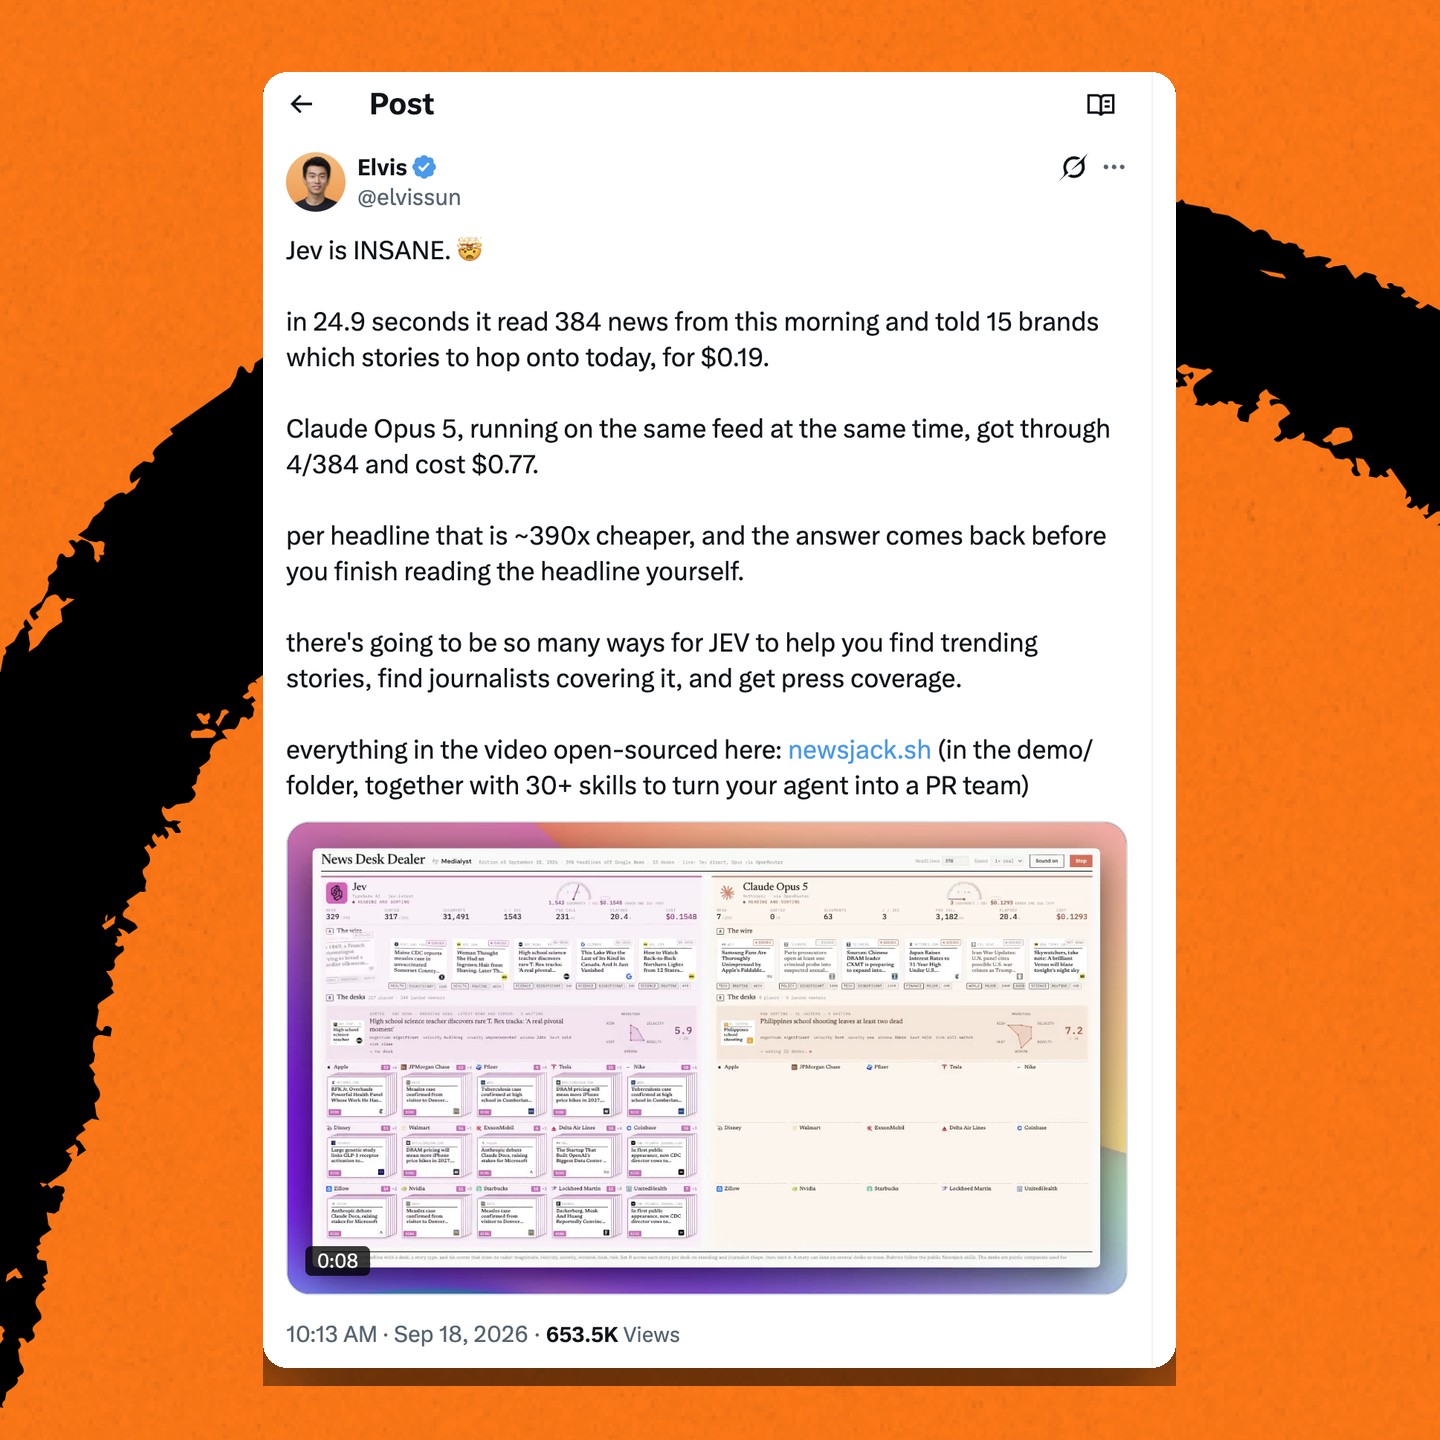
“A good lesson I’ve learned at Every is that, when you see content showing someone doing something cool with AI that you want to do, you can give the content to AI and say, ‘Just do this,’” Douglas says.
So he gave the post to his Grok bot and asked, “Can you just do this with Jev?” The bot asked for an API key and took it from there. Douglas’s morning pulse now surfaces more stories Every can weigh in on. Before Jev, Grok reviewed fewer than 20 posts in a typical run; with Jev, it reviews more than 500—including ones he hadn’t seen on X.
Try it this week: Give Codex or Claude Code a demo with this request, “Help me adapt this for [my task]. Tell me what you need from me and build a version I can test.”
If you don’t have a demo in mind, here are a few that attracted a lot of attention on X. Or ask your agent to find you one.
Inside Every
Intent-based software
Jack built a Jev demo that illustrates how, when given multiple signals and a fixed set of possible actions, the model can appear to interpret intent.
He vibe coded a voice- and gesture-controlled digital canvas using tldraw. After calibrating the app’s hand tracking, Jack can point at the canvas and say, “Make a blue square here,” for example, and a blue square will appear beneath where he’s pointing.
Under the hood, the browser transcribes Jack’s speech, records his fingertip’s coordinates, and describes the canvas as a list of shapes and their attributes. The app sends that information to Jev, which answers several questions at once: Which shape does he want to change? What color or size does he want? Where should it go? Ordinary code then maps Jev’s answers to tldraw commands that create, resize, move, select, or delete shapes.
“If you were to ask even the fastest language models to do this, each interaction would probably take a second or two at best,” Jack says. “It’d break the feeling of a responsive, real-time interface.”
Jev doesn’t accept images as inputs and therefore never “sees” the canvas. Instead, it quickly answers a set of smaller questions of the data it has about the state of the canvas and Jack’s commands that together help answer the bigger questions of “What does Jack want to do?”
“I come back to this idea of quickly converting intent into action,” Jack says. “That’s a cool thing Jev is letting people do, interaction-wise.”
Data point
4.2 cents
That’s Jev’s price per million input tokens (output is free). For comparison, here’s the price per million tokens for other popular models:
Gemini 3.7 Flash: $0.75 input, $3.75 output
Haiku 4.5: $1 input, $5 output
Sol: $4 input, $20 output
Astra: $10 input, $50 output
Fable 5.1: $10 input, $50 output
Laura Entis is a staff writer at Every. To read more essays like this, subscribe to Every, and follow us on X at @every and on LinkedIn.
Everyone’s a builder now. Every All Access gets you the full membership plus the Builder Pack—$9,000+ in credits for the tools we build with.
See how good you are at using AI—and learn how to get better
Sign in to read for free and get your AI assessment prompt.
Continue with GoogleView all login options Continue with Google