
We use analytics and advertising tools by default. You can update this anytime.
Katie Parrott is a staff writer. She writes Working Overtime and contributes to Vibe Checks, Source Code, and Context Window.
A new lab says the sameness of AI prose is a training problem. It made the writing less predictable—but not necessarily any better.
Aug 24, 2026 · 8 min readUpdated Sep 15, 2026

Was this newsletter forwarded to you? Sign up to get it in your inbox.
Imagine a cover band that technically knows every song ever written but only has one arrangement. The melody consists of the same set of chords. The guitarist plays the same solo whether they are covering “Landslide” or “Party in the U.S.A.” By the fourth song, you are tired, and more than a little angry.
That’s what reading raw AI writing can feel like. The first few items you read, nothing trips your alarm—it’s just competent, if somewhat boring, writing. Then you keep seeing the same moves again and again: the patterns of three, the “not X, but Y,” the short sentence hanging off the back end of the paragraph that exists to do nothing but tell you that what you just read “matters.” Eventually you stop absorbing what the words are trying to communicate.
I’ve said before that it feels like model progress on writing at the major labs has stalled. Maybe no one model can be all things to all people, or maybe OpenAI, Anthropic, and Google have bigger, more lucrative fish to fry in the coding space. On the one hand, fair enough. But as an AI-pilled writer, I can’t help feeling a little left out. It reminds me of high school, when the AP English paper deadline got pushed back after I’d already written it, because obviously the AP Physics exam took precedence.
So when I heard about a new, writing-focused model, I immediately queued it up for a Vibe Check.
Deft is a new research lab and model focused on “better writing.” The lab was cofounded by Justin Murphy, a former political-science professor turned writer and publisher, and an AI researcher who goes by the name Rosmine. Its first release, DFT v1, is a writing model post-trained with the lab’s custom fine-tuning method. Initially introduced in June, DFT v1 entered public beta last week.
The team behind Deft has a theory about why AI writing feels the way it does: LLMs have a distribution problem. Not in the sense of whether the writing gets read by people—it does, although not always happily. Deft is concerned with the distribution of the words themselves: which phrases recur, how sentences tend to begin and end, and whether a large body of output collapses toward the same handful of moves. The company’s bet is that, if you train a model to match the distribution of human writing across a batch of documents—not merely make each individual response acceptable—you’ll get prose with more range.
The engine driving Deft’s approach is a method called “distribution fine-tuning,” or DFT, a post-training step applied after a model has learned to predict language. Typical fine-tuning grades one response at a time, meaning that 1,000 responses can each pass inspection while in the aggregate, they are repeating the same openings and rhythms. DFT instead compares batches of model outputs with batches of human writing, then adjusts the model when the two distributions differ.
The resulting model is called DFT v1. On Deft’s tests, it produced a distribution of writing closer to the human samples than a conventional fine-tune of the same size. The basic claim is that changing the post-training will yield more range.
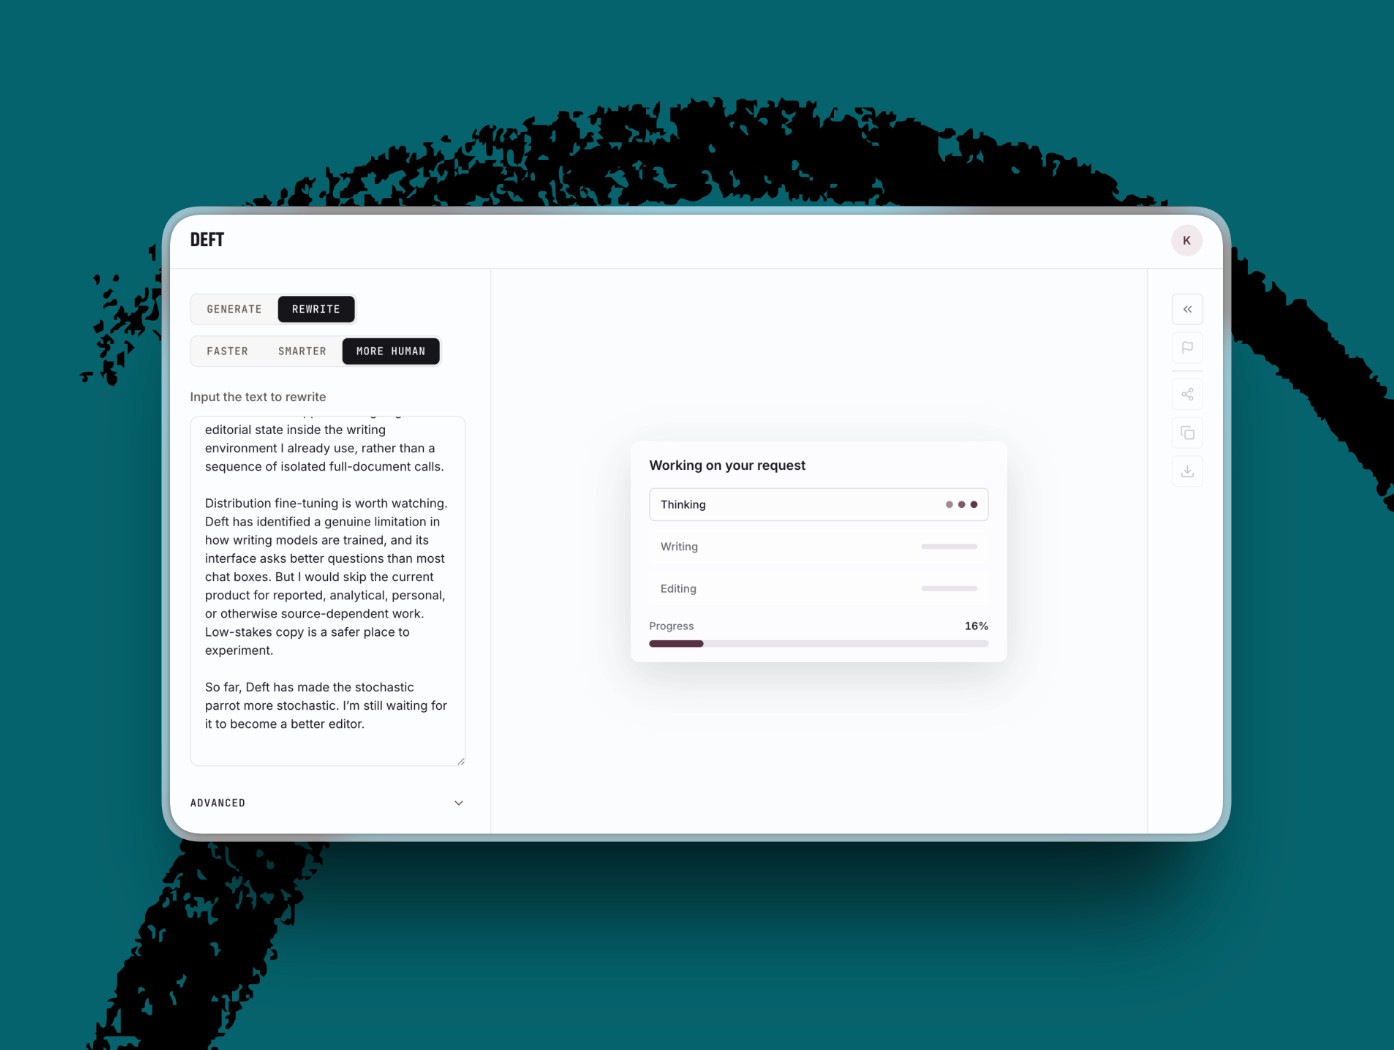
For now, the model is available via Deft’s website and paid API. You supply a prompt, choose whether you want the model to work faster, smarter, or “more human,” and choose an output format from a selection of four: news article, analytical essay, SEO article, or company blog. Advanced controls let you describe your writing style or paste in an example for the model to emulate. It also includes an option to choose between “strict” and “creative” modes. Strict mode promises to “use only the details in your prompt”; creative mode can invent supporting specifics.
To test the model, I had Deft write an analytical essay on how AI is affecting jobs and an SEO article on how to write an AI style guide. I asked it to draft from scratch and then to rewrite an existing draft I’d had GPT-5.6 Sol generate for the same assignment. And I used it through the web console and the API.
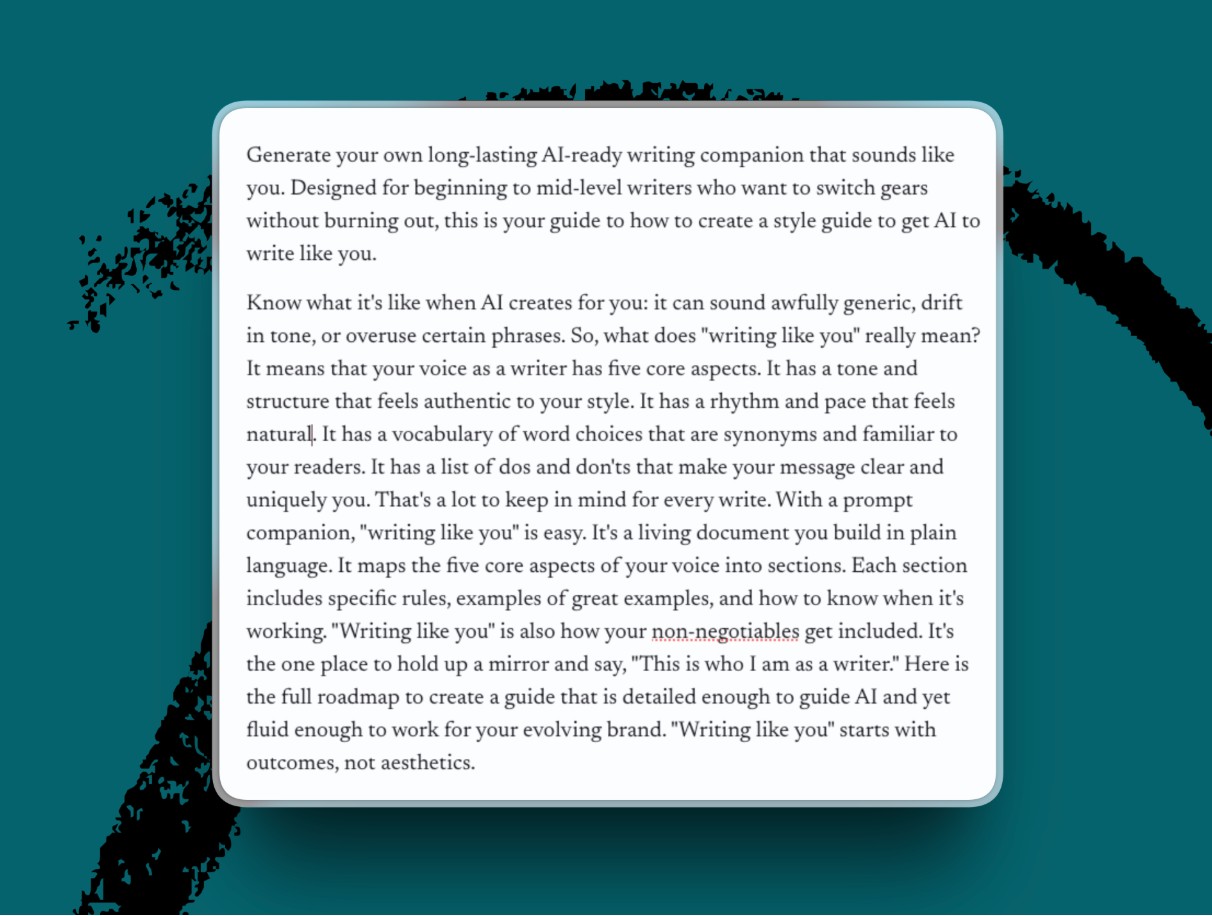
At the sentence level, Deft’s prose was more varied and surprising than most AI writing I read. It was also dense, hard to parse, and poorly sequenced. The Deft web interface includes a reading score, and it rated its own output at an 11th-grade reading level. (For context, 54 percent of U.S. adults read at a sixth-grade level or lower, according to the National Literacy Institute). The introduction to the SEO article gave me jumbled phrases like “a vocabulary of word choices that are synonyms,” “examples of great examples,” and “That’s a lot to keep in mind for every write.” The phrases were unusual. They were not clear.
For the analytical essay, I set the model to strict mode and gave it a detailed brief with main points and sources. Deft introduced a new idea in its draft about workers being pushed onto AI platforms by managers, unions, or a company’s majority owner. None of those details appeared in my brief.
I wanted to see if Deft worked better inside my normal writing setup, so I connected its API to Codex. I learned that the API’s capabilities are rather limited, at least for now. Instead of giving you access to the model itself, the API lets you send assignments from another platform to Deft to be completed inside the Deft system and sent back again. In other words, you still get chunks of completed text rather than collaborating with the model on how the piece takes shape.
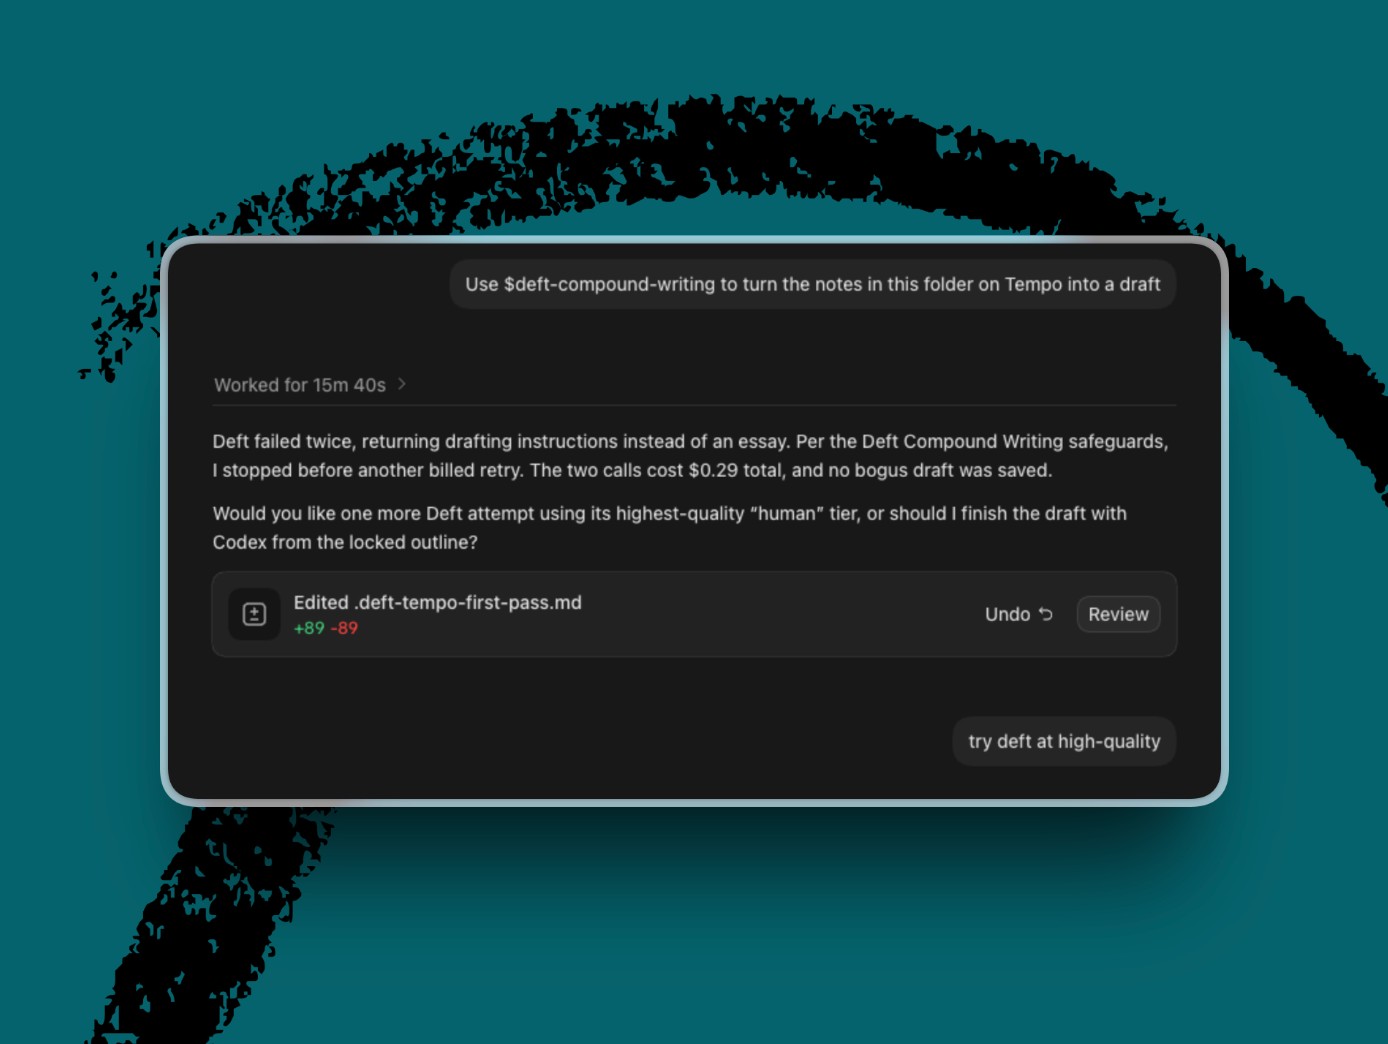
I asked Codex to assemble the brief, including an outline, plus my voice rules, then sent that packet to Deft via the API. The first two attempts returned drafting instructions instead of the essay. On the third, I used Deft’s highest-quality setting. It wrote half the piece, stopped, and invented dates, dialogue, product history, screenshots, behaviors, and emotions that weren’t in my sources—even though I set the model to strict. I paid $0.49 and got no usable draft.
Deft has shown that it can produce writing that is less predictable than most models. What it hasn’t proven yet is that it can generate writing that is better. Writing produced by models like GPT-5.6 Sol or Sonnet 5 may have “AI smell,” but the telltale signs are predictable enough at this point that I know how to spot them and how to break them up. The editing lift with DFT v1’s prose is similar—but with less clarity about where to start.
The model needs a better grasp of information hierarchy, sequencing, and reader theory of mind. A strong draft does more than vary its syntax. Good writing directs attention. It knows when a term needs explaining, when evidence needs context, and how to order information in a way that makes the reader lean in. Deft often seemed to make those decisions locally, sentence by sentence, without a stable model of the whole piece.
I also want the ability to iterate with the model. Deft is oriented around complete-document generation, but my writing process rarely moves from brief to finished draft in one jump. I want to go back and forth with the model, keep certain parts of its output and rework others, and use the whole arsenal of tools I’ve built to help models write more like me.
Strict mode also needs to mean strict. I want clear rules about sources, instructions that persist, and a way to distinguish facts the model must preserve from possibilities it has permission to develop. Deft already offers an API. I want it to work inside my compound writing workflow. I should be able to say, “Keep this claim exactly as written, move the jobs section up, and rewrite only the transition,” without Deft returning an entirely new essay.
Five years ago, researchers Emily M. Bender, Timnit Gebru, Agnelina McMillan-Major, and “Schmargaret Schmitchell” coined the term “stochastic parrot” to describe LLMs—“stochastic” because language models generate from probabilities, and “parrot” because they can mimic linguistic form without knowing the meaning of the words. Even today, LLMs produce text that is not grounded in communicative intent, a model of the world, or a model of the reader.
Deft intervenes in the stochastic half of the metaphor. DFT changes the distribution of patterns a model reaches for across a batch of outputs, giving the parrot a broader repertoire; the results are still probabilistic, but less probable. DFT’s writing can sound more surprising, but based on my testing, variety alone can’t fix what ails AI writing.
Deft is a promising demonstration that the sameness of AI prose can be treated as a training problem. For a brand-new lab working with an experimental model, isolating one tractable layer of that stack is a strong start. I wouldn’t yet use Deft for day-to-day work, but I’m curious to see where the model goes, what the lab tackles next, and what other labs may follow.
Disclosure: We tested Deft through its public website and paid API. Deft had no input on the development of this review.
Everyone’s a builder now. Every All Access gets you the full membership plus the Builder Pack—$9,000+ in credits for the tools we build with.
Sign in to read for free and get your AI assessment prompt.
Continue with GoogleView all login options
 Continue with Google